Shrinking Toward Zero
4 min read
We want to estimate \(d\) unknown numbers \(\theta_1,\ldots,\theta_d\). Suppose we observe each one with Gaussian noise:
\[ x_i=\theta_i+\epsilon_i, \qquad \epsilon_i\sim\mathcal N(0,\sigma^2), \qquad i=1,\ldots,d. \]
The noises are independent, and their common variance \(\sigma^2>0\) is known. The unknown numbers stay fixed; expectations average over the noise in repeated measurements.
Using the Measurements
The simplest estimate of \(\theta_i\) is \(x_i\) itself. Its expected error is zero:
\[ \mathbb E[x_i-\theta_i]=\mathbb E[\epsilon_i]=0. \]
Its variance is:
\[ \operatorname{Var}(x_i)=\operatorname{Var}(\epsilon_i)=\sigma^2. \]
We compare estimates by adding their mean squared errors. Write \(\boldsymbol\theta=(\theta_1,\ldots,\theta_d)\) and \(\mathbf x=(x_1,\ldots,x_d)\), and let \(R(\boldsymbol\theta,\widehat{\boldsymbol\theta})\) denote this expected total error for an estimator \(\widehat{\boldsymbol\theta}\). For the measurements themselves:
\[ \begin{aligned} R(\boldsymbol\theta,\mathbf x) &=\mathbb E\!\left[\sum_{i=1}^d(x_i-\theta_i)^2\right]\\ &=\sum_{i=1}^d\mathbb E[\epsilon_i^2]\\ &=\sum_{i=1}^d\left(\operatorname{Var}(\epsilon_i)+(\mathbb E[\epsilon_i])^2\right)\\ &=d\sigma^2. \end{aligned} \]
Every estimate contributes one noise variance to the total. We can lower this total even though the measurements are already unbiased.
Reducing the Variance
Try multiplying every measurement by a fixed fraction \(\alpha\in[0,1]\). The new estimate is \(\widehat\theta_i=\alpha x_i\), whose variance is:
\[ \operatorname{Var}(\alpha x_i) =\alpha^2\operatorname{Var}(x_i) =\alpha^2\sigma^2. \]
It also has a bias, the difference between its expected value and the truth:
\[ \begin{aligned} \mathbb E[\alpha x_i]-\theta_i &=\alpha\mathbb E[x_i]-\theta_i\\ &=(\alpha-1)\theta_i. \end{aligned} \]
Mean squared error is variance plus squared bias, so the total becomes:
\[ \begin{aligned} R(\boldsymbol\theta,\alpha\mathbf x) &=\sum_{i=1}^d\left(\alpha^2\sigma^2+(1-\alpha)^2\theta_i^2\right)\\ &=\underbrace{\alpha^2d\sigma^2}_{\text{variance}} +\underbrace{(1-\alpha)^2\|\boldsymbol\theta\|^2}_{\text{squared bias}}, \end{aligned} \]
where \(\|\boldsymbol\theta\|^2=\sum_i\theta_i^2\). When the true values are near zero, the variance reduction can outweigh the added bias. For any fixed \(\alpha<1\), however, the squared bias grows without bound as \(\|\boldsymbol\theta\|\) grows. That choice will eventually have more error than the original \(d\sigma^2\).
The plot separates these two contributions for six quantities. Change the true signal length, then adjust the fraction retained to see which choices reduce the total error.
Bias and Variance of Fixed Shrinkage
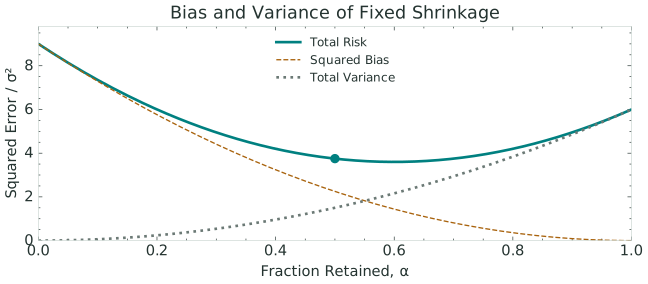
The best fixed fraction depends on the unknown true values. To improve on the measurements for every possible true vector, we need the amount of shrinkage to depend on the observations.
Shrinkage Chosen from the Data
For \(d\ge3\), the James–Stein estimator uses the observed squared length \(\|\mathbf x\|^2=\sum_i x_i^2\) [JS, ’61]:
\[ \widehat{\boldsymbol\theta}_{\mathrm{JS}}(\mathbf x) =\left(1-\frac{(d-2)\sigma^2}{\|\mathbf x\|^2}\right)\mathbf x. \]
Larger observed lengths make the multiplier closer to one. Every estimate uses the same multiplier, so each uses information from all \(d\) measurements. When \(\|\mathbf x\|^2<(d-2)\sigma^2\), the multiplier is negative and the estimate points in the opposite direction. At \(\mathbf x=\mathbf0\), define the estimate to be zero; this event has probability zero.
This estimator has expected total squared error strictly below \(d\sigma^2\) for every \(\boldsymbol\theta\). To calculate it, we cannot substitute this random multiplier into the fixed-\(\alpha\) calculation: the multiplier and the measurements depend on the same noise.
Calculating the Error
Write the estimate as \(\mathbf x+\mathbf g(\mathbf x)\), where \(\mathbf g\) is its correction. Expanding the squared error gives:
\[ \begin{aligned} R(\boldsymbol\theta,\mathbf x+\mathbf g) &=\mathbb E\!\left[\|\mathbf x-\boldsymbol\theta+\mathbf g(\mathbf x)\|^2\right]\\ &=d\sigma^2+\mathbb E\!\left[\|\mathbf g(\mathbf x)\|^2\right] +2\sum_{i=1}^d\mathbb E\!\left[(x_i-\theta_i)g_i(\mathbf x)\right]. \end{aligned} \]
The cross term contains the unknown means. For Gaussian noise, Stein’s identity replaces it with derivatives of the correction [S, ’81]:
\[ \mathbb E\!\left[(x_i-\theta_i)g_i(\mathbf x)\right] =\sigma^2\mathbb E\!\left[\frac{\partial g_i}{\partial x_i}(\mathbf x)\right]. \]
This identity requires sufficient regularity, integrable absolute derivatives, and vanishing integration boundary terms. The proof also checks the singularity of the James–Stein correction at zero.
Proof of Stein’s identity
Condition on all coordinates except \(x_i\). Independence leaves \(x_i\) with its Gaussian density \(p_i\), whose derivative is:
\[ p_i'(x_i)=-\frac{x_i-\theta_i}{\sigma^2}p_i(x_i). \]
Substitute this derivative and integrate by parts:
\[ \begin{aligned} \int_{-\infty}^{\infty}(x_i-\theta_i)g_i(\mathbf x)p_i(x_i)\,dx_i &=-\sigma^2\int_{-\infty}^{\infty}g_i(\mathbf x)p_i'(x_i)\,dx_i\\ &=-\sigma^2\left[g_i(\mathbf x)p_i(x_i)\right]_{-\infty}^{\infty} +\sigma^2\int_{-\infty}^{\infty}\frac{\partial g_i}{\partial x_i}(\mathbf x)p_i(x_i)\,dx_i\\ &=\sigma^2\int_{-\infty}^{\infty}\frac{\partial g_i}{\partial x_i}(\mathbf x)p_i(x_i)\,dx_i. \end{aligned} \]
The boundary term vanishes under the stated conditions. Averaging over the other coordinates gives the identity. Continuously differentiable functions and derivatives of at most polynomial growth satisfy these Gaussian integrability conditions.
For the James–Stein correction, the required reciprocal expectation is finite when \(d>2\). Near zero, the Gaussian density is bounded and a spherical shell of radius \(r\) has volume proportional to \(r^{d-1}\,dr\). The possible singularity is therefore controlled by:
\[ \int_0^1\frac{r^{d-1}}{r^2}\,dr =\int_0^1r^{d-3}\,dr<\infty \qquad(d>2). \]
For integration by parts, exclude a ball of radius \(\varepsilon\) around zero. Its boundary area is of order \(\varepsilon^{d-1}\) and the correction is of order \(1/\varepsilon\), so the extra boundary term is of order \(\varepsilon^{d-2}\) and vanishes for \(d>2\). The Gaussian density makes the boundary term at infinity vanish as well.
Applying the identity to the cross terms gives:
\[ R(\boldsymbol\theta,\mathbf x+\mathbf g) =d\sigma^2+ \mathbb E\!\left[ \|\mathbf g(\mathbf x)\|^2 +2\sigma^2\sum_{i=1}^d\frac{\partial g_i}{\partial x_i}(\mathbf x) \right]. \]
For the James–Stein correction, leave the coefficient as a positive constant \(c\) for now:
\[ g_i(\mathbf x)=-\frac{c\sigma^2x_i}{\|\mathbf x\|^2}. \]
Its squared size is:
\[ \begin{aligned} \|\mathbf g(\mathbf x)\|^2 &=\frac{c^2\sigma^4\sum_i x_i^2}{\|\mathbf x\|^4}\\ &=\frac{c^2\sigma^4}{\|\mathbf x\|^2}. \end{aligned} \]
Differentiating the numerator and denominator gives:
\[ \frac{\partial g_i}{\partial x_i} =-c\sigma^2\left(\frac1{\|\mathbf x\|^2}-\frac{2x_i^2}{\|\mathbf x\|^4}\right). \]
Summing over all \(d\) coordinates gives:
\[ \begin{aligned} \sum_{i=1}^d\frac{\partial g_i}{\partial x_i} &=-c\sigma^2\left(\frac{d}{\|\mathbf x\|^2}-\frac{2\sum_i x_i^2}{\|\mathbf x\|^4}\right)\\ &=-\frac{c\sigma^2(d-2)}{\|\mathbf x\|^2}. \end{aligned} \]
The \(d\) comes from differentiating the \(d\) numerators; the two comes from differentiating their shared squared length. The squared correction and the derivative contribution have the same denominator. Substituting both into the error calculation therefore gives:
\[ \begin{aligned} R(\boldsymbol\theta,\mathbf x+\mathbf g)-d\sigma^2 &=\sigma^4\bigl[c^2-2c(d-2)\bigr] \mathbb E\!\left[\frac1{\|\mathbf x\|^2}\right]\\ &=\sigma^4\bigl[(c-(d-2))^2-(d-2)^2\bigr] \mathbb E\!\left[\frac1{\|\mathbf x\|^2}\right]. \end{aligned} \]
The reciprocal expectation is positive and finite for \(d>2\).
Completing the square shows that \(c=d-2\) minimizes the error within this family, regardless of the unknown true values. For \(d\ge3\), it gives:
\[ R(\boldsymbol\theta,\widehat{\boldsymbol\theta}_{\mathrm{JS}}) =d\sigma^2-(d-2)^2\sigma^4 \mathbb E\!\left[\frac1{\|\mathbf x\|^2}\right] <d\sigma^2. \]
The plot divides each method’s expected error by \(d\sigma^2\), so using the measurements themselves gives a horizontal line at one. Change the dimension or the true signal length to compare James–Stein with retaining a fixed half of every measurement. The curves evaluate expected errors numerically, without simulation noise.
Expected Total Error Across True Means
The vertical scale stops at twice the original risk; the half-shrinkage curve continues above the plot.
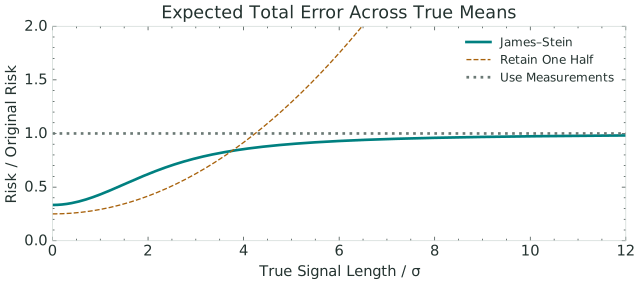
The guarantee concerns the expected sum of squared errors across all \(d\) quantities. An individual estimate, or the total error on a particular noisy observation, can still get worse.