Neyman Allocation
4 min read
Suppose we want to estimate the average of several group means using a fixed number of observations. We can choose how many observations to collect from each group, and want the resulting estimate to have the smallest possible variance. This problem appears in stratified Monte Carlo integration, where groups can be equal-volume regions, and in model evaluation, where we might average performance across equally important datasets. Neyman allocation, developed for stratified survey sampling, assigns more observations to groups with greater variability [Neyman, JRSS ’34].
Variance of the Estimate
Let the \(k\) groups have means \(\mu_h\) and positive standard deviations \(\sigma_h\), for \(h=1,\ldots,k\). Our target is the average of their means:
\[ \mu=\frac{1}{k}\sum_{h=1}^k\mu_h. \]
Fix a positive integer sample count \(m_h\) for each group, with total budget \(\sum_{h=1}^k m_h=m\ge k\). Draw observations independently within and across groups. Let \(G_h\) index the \(m_h\) observations drawn from group \(h\), so each \(x_i\) with \(i\in G_h\) has mean \(\mu_h\) and variance \(\sigma_h^2\). The group average and our estimate are:
\[ \bar{x}_h=\frac{1}{m_h}\sum_{i\in G_h}x_i, \qquad \hat{\mu}=\frac{1}{k}\sum_{h=1}^k\bar{x}_h. \]
Each group average is unbiased for its mean, so \(\hat{\mu}\) is unbiased for \(\mu\). For its variance, first consider a single group:
\[\begin{align*} \operatorname{Var}(\bar{x}_h) &=\frac{1}{m_h^2}\operatorname{Var}\!\left(\sum_{i\in G_h}x_i\right)\\ &=\frac{1}{m_h^2}\sum_{i\in G_h}\operatorname{Var}(x_i)\\ &=\frac{m_h\sigma_h^2}{m_h^2}\\ &=\frac{\sigma_h^2}{m_h}. \end{align*}\]
Scaling by \(1/m_h\) scales variance by its square; independence lets us add the variances of the \(m_h\) observations. Independence across groups then gives the total variance:
\[\begin{align*} \operatorname{Var}(\hat{\mu}) &=\frac{1}{k^2}\sum_{h=1}^k\operatorname{Var}(\bar{x}_h)\\ &=\frac{1}{k^2}\sum_{h=1}^k\frac{\sigma_h^2}{m_h}. \end{align*}\]
More samples make a group average more precise while its weight in the estimate stays \(1/k\). We can therefore reduce the total variance by changing the sample counts.
Equal Marginal Gains
Temporarily allow the counts to be positive real numbers. The marginal reduction in total variance from increasing \(m_h\) is:
\[ -\frac{\partial}{\partial m_h}\operatorname{Var}(\hat{\mu}) =\frac{\sigma_h^2}{k^2m_h^2}. \]
If one group offered a larger reduction than another, moving a little sampling effort to it would lower the variance without changing the budget. At the optimum these marginal gains must agree, which requires \(m_h\) to be proportional to \(\sigma_h\). A group with three times the standard deviation receives three times the observations.
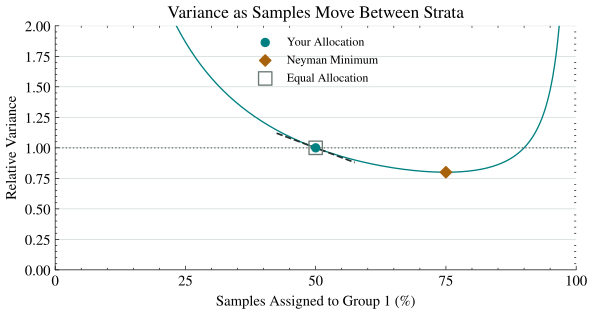
The plot shows two equally weighted groups, initially with standard deviations in a three-to-one ratio. Allocating 75% of the observations to group 1 then lowers variance by 20% compared with splitting the budget equally. Move samples between them or change that ratio; the tangent becomes horizontal when the marginal gains agree.
Variance as Samples Move Between Strata
The curve uses continuous sample shares; all allocations use the same sample count. Both group means have weight 1/2. Variance 1 is the equal allocation.
The Lagrange Multiplier
The common factor \(1/k^2\) does not affect which allocation minimizes variance. We minimize \(\sum_h\sigma_h^2/m_h\) subject to \(\sum_h m_h=m\).
Claim: The variance-minimizing continuous allocation is:
\[ m_h^*=m\frac{\sigma_h}{\sum_{j=1}^k\sigma_j}. \]
Proof with a Lagrange multiplier
Introduce a multiplier \(\lambda\) for the budget constraint:
\[ \mathcal{L}(m_1,\ldots,m_k,\lambda) =\sum_{h=1}^k\frac{\sigma_h^2}{m_h} +\lambda\left(\sum_{h=1}^k m_h-m\right). \]
At a minimum, differentiating with respect to each count gives:
\[\begin{align*} 0&=\frac{\partial\mathcal{L}}{\partial m_h}\\ &=-\frac{\sigma_h^2}{m_h^2}+\lambda. \end{align*}\]
Taking the positive square root yields:
\[ m_h=\frac{\sigma_h}{\sqrt{\lambda}}. \]
The counts sum to \(m\), which determines the multiplier:
\[\begin{align*} m&=\frac{\sum_{h=1}^k\sigma_h}{\sqrt{\lambda}},\\ \sqrt{\lambda}&=\frac{\sum_{h=1}^k\sigma_h}{m}. \end{align*}\]
Substitution gives the claimed allocation. Each objective term has positive second derivative \(2\sigma_h^2/m_h^3\), so the objective is strictly convex on positive counts. The constraint is linear, making this stationary point the unique global minimum.
Actual sample counts must be integers, so rounding must preserve the budget and leave at least one observation in each group.
Learning the Standard Deviations
We assumed access to the standard deviations, yet usually need observations to estimate them. This creates a chicken-and-egg problem: we need to know which groups vary most to decide where to sample.
Side information can help: historical observations or a cheap preliminary measurement may indicate which groups need more attention. Adaptive sampling learns during collection, starting with observations from every group and revising the allocation as estimates improve. Carpentier, Munos, and Antos use upper confidence bounds on estimated standard deviations, so a group does not lose its sampling budget merely because its first observations happened to look similar [CMA, JMLR ’15].
A simple approach takes an independent pilot sample, fixes the allocation using it, and computes the estimate from fresh observations. Conditional on the pilot, the counts are fixed and the variance calculation above applies. The pilot consumes part of the budget, and inaccurate standard deviations can still lead to poor allocations. Reusing observations while adaptively deciding the counts needs a separate analysis, since the counts then depend on the data being averaged. Learning the standard deviations is itself part of the sampling problem.